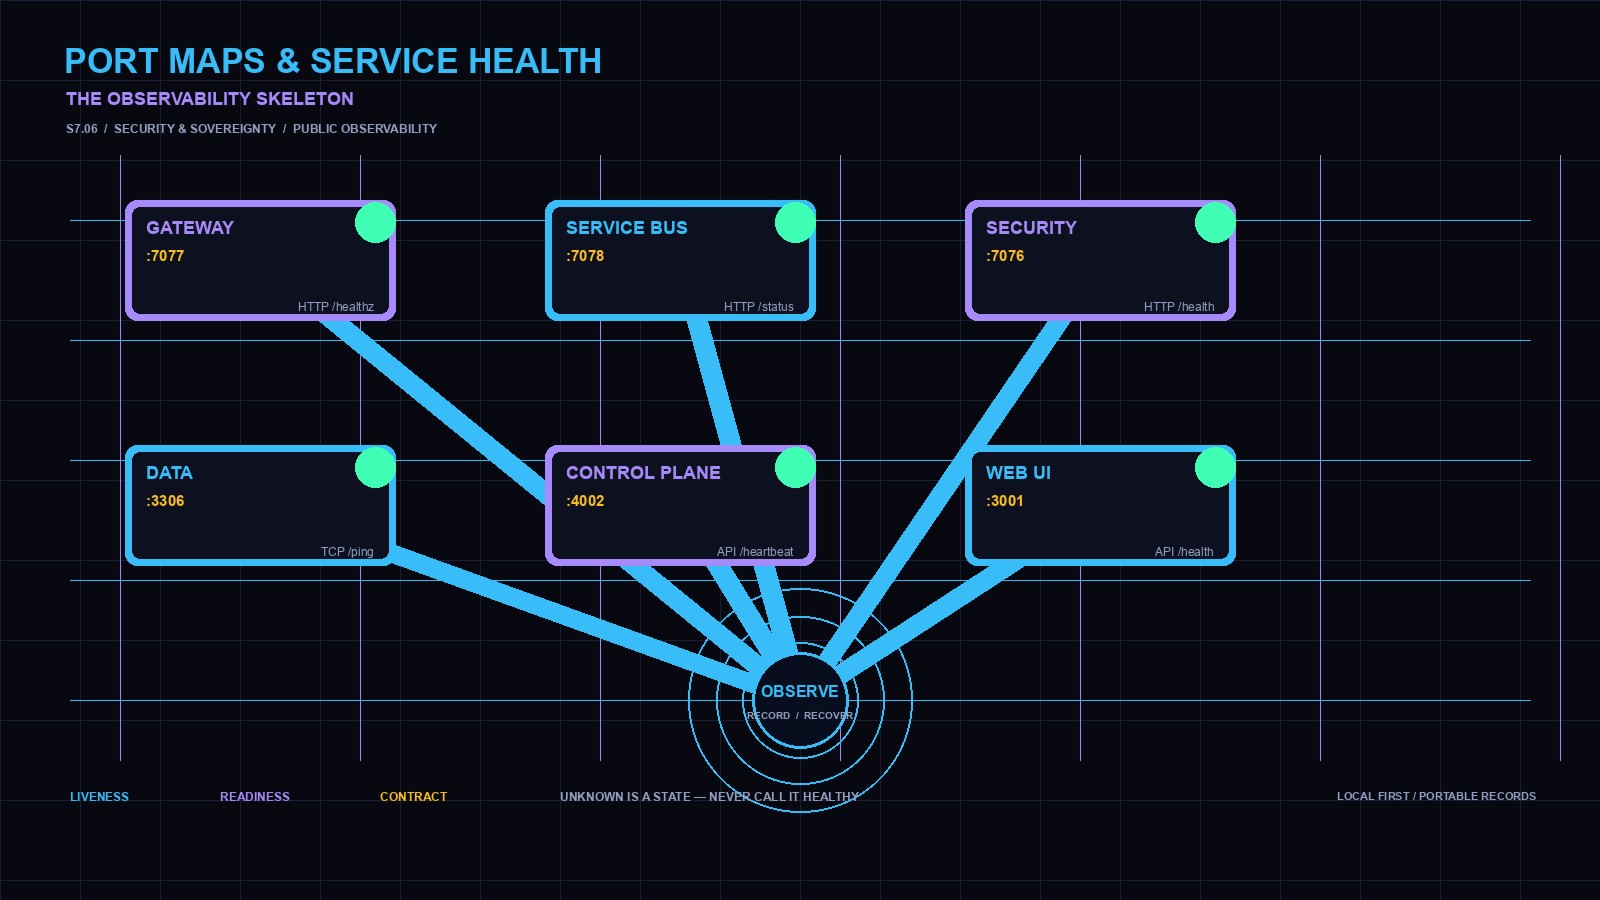

Port Maps and Service Health: The Observability Skeleton
A port number looks trivial until a fleet depends on it. One number can be the difference between a gateway accepting work and a board losing state, a database accepting writes and returning cached data, or a public page resolving while its origin is unreachable. The first job of a port map is not visual elegance. It is continuity: name every service, bind it to a stable address, and make that claim inspectable.
That makes the map an information artifact. It answers three questions for every node: what is this service called, where should its traffic arrive, and how will the system know it is working? Without those answers, every incident begins with oral history. Someone remembers the dashboard is “on three thousand-something,” another person searches shell history, and the fleet spends its first minutes reconstructing topology instead of repairing it.
A useful map separates the service from its exposure. The service has an internal role; the address has a network boundary. A public tunnel, a private LAN endpoint, and a container-only socket may reach the same process, but they do not carry the same risk. Naming those paths prevents a convenient local route from quietly becoming an internet-facing promise.
Make the topology machine-readable
A diagram can explain a stack to a person. A machine-readable map can stop a stack from lying to itself. Give each service a stable identifier, role, transport, address, expected dependency, and health signal. Record the expected relationship beside the address so that a process listening on a port is not mistaken for a process ready to receive work.
This is where a topology-as-code check earns its place. Before a new service is declared deployed, verify that its identifier is unique, its address is reserved, its route is allowed, and its health signal exists. A missing field should fail the release. The result is an architecture that can be moved, audited, and handed over without relying on memory.
Open ports are weaker than meaningful health
A listening socket proves very little. A process can accept a connection while its database is gone, its queue is full, its filesystem is read-only, or its clock is wrong. The familiar /healthz response is useful only if the endpoint represents a real contract. If it returns success before initialization, stale metrics, or an unreachable dependency can still break the service, the green light is a historical claim rather than current information.
Name the check after what it proves. Liveness asks whether the process can restart or remain running. Readiness asks whether it can handle the next unit of expected work. Contract health asks whether a bounded operation produces a result that still satisfies the service’s role. These are not interchangeable labels; each is a different boundary between “running” and “useful.”
Three tiers keep cost proportional to risk
Not every service needs a transaction on every probe. A three-tier model is practical.
Liveness checks are cheap and frequent. They confirm the process, listener, or managed task is present. Use them to detect hard failure and to provide a fast restart signal, not to claim that business behavior is correct.
Readiness checks run on a measured interval and inspect the capability needed for the next task. A gateway confirms it can reach its expected upstream route. A board confirms its write path. A media pipeline confirms its workspace and destination. This tier catches degradation before a user does.
Contract checks are slower and reserved for stateful or critical services. They verify a small representative result, compare freshness, and prove that dependent state is readable. Use them to detect silent corruption and stale truth, not to create a continuous synthetic workload.
The discipline is proportionality. Too little probing misses a half-dead system. Too much probing becomes a second workload that can cause the outage it was meant to detect. Choose the cheapest check that can falsify the claim you care about, then escalate only when the lower tier changes state.
A status endpoint is still a schema
The moment a health check feeds a dashboard, an agent, or a recovery routine, its response becomes an API. Give the status a stable schema: overall state, component state, observed time, check age, latency where useful, and a short reason. Keep the schema smaller than the implementation. A dashboard should need no private database connection to understand the answer.
Freshness deserves its own field. A status captured one minute ago is not equivalent to a status captured one hour ago. Mark unavailable data explicitly; never convert silence into healthy. If a collector stops, the system should report “unknown” or “stale” and preserve the last observed state with its timestamp. Continuity beats completion, and continuity includes the period in which the monitor itself was silent.
An agentic system adds one requirement: the state must support a bounded action. “Degraded” alone is an adjective. “Database readiness failed twice; stop dispatching writes and route read-only traffic” is an operating decision. The health contract should expose enough context to let the responsible layer choose the next safe move without inventing certainty.
From observation to recovery
Observability becomes operational when evidence reaches an owner: a probe records state, a gate decides whether to continue, and the response is written back. The path must end in a recorded decision rather than a notification that disappears.
For a reversible local failure, the system can retry, restart, or reroute within an explicit boundary. For a permission, storage, or data-integrity failure, automation should stop rather than make the condition harder to inspect. The laser line here is simple: public documentation can describe the decision boundary, but not the protected credentials, raw customer data, or hidden formulas that drive it.
After recovery, keep the result. Record the original symptom, the checks that bounded the failure, the action taken, and the first successful verification. That record gives the next worker a head start. It also turns a one-off repair into operational memory: the fleet learns which signal deserves attention and which alert is noise.
Local-first changes the trade-off
A local-first stack does not pretend that central dashboards, remote metrics stores, or notification services do not exist. It changes the authority boundary. The source of truth and the first useful health signal should remain available when a network dependency disappears. Remote services can enrich the view, but they should not become the only way to know whether a local system is safe to use.
That constraint rewards a legible skeleton: a machine-readable port map, explicit health contracts, local logs, and a bounded decision path can be inspected, backed up, and moved with the system.
The result is not maximal instrumentation. It is trustworthy continuity. When one service degrades, the fleet can name the boundary, preserve the evidence, and choose a reversible next step while the rest of the system remains intelligible.
Seven questions for a service-health review
Before declaring the observability skeleton complete, ask:
- Can I name every critical service and its expected route?
- Is every route classified as local, private, or public?
- Does each service have a liveness or readiness signal that proves a real capability?
- Does every health record include time, freshness, and a reason?
- Can an agent distinguish unknown, degraded, and healthy?
- Is there a bounded action for each failure class?
- Can I inspect the evidence after the incident without asking the operator to remember it?
The observability skeleton is complete when the system can answer these questions without crossing an unrecorded dependency. A dashboard can make the answers visible. The skeleton is what makes them true.